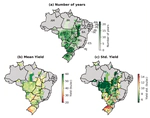
Many countries report crop yields only for large administrative units, so models trained on coarse records must be applied at finer scales, where few samples and scale-dependent relationships degrade accuracy. A machine learning model trained on field-level soybean yields in the US Midwest was fine-tuned with Brazilian state-by-year records, a technique called transfer learning, then used to predict municipal yields from 2001 to 2021. Transfer across scales rather than across regions had rarely been tested. Without any municipal training data, explained yield variance rose from 0.29 to 0.44, though transfer added little where fine-scale data were plentiful.